Showing posts with label IBM Cloud. Show all posts

Wednesday, March 5, 2025

Understanding IBM Redis: A Comprehensive Technical Overview


This document provides an in-depth analysis of IBM Redis, exploring its features, advantages, and disadvantages, as well as comparing it with similar offerings from AWS, Azure, and Google. We will also discuss when to choose IBM Redis for your memory database needs, supported by real-time use cases. Additionally, we will provide Terraform code for provisioning an IBM Redis memory database and outline best practices to consider when using this technology.


What is IBM Redis?

IBM Redis is a fully managed, in-memory data structure store that can be used as a database, cache, and message broker. It is built on the popular open-source Redis technology and offers two primary modes: cache and persistence.

  • Cache Mode: In this mode, IBM Redis functions as a high-speed cache, storing frequently accessed data in memory to reduce latency and improve application performance. This is particularly useful for applications that require quick data retrieval, such as web applications and microservices.

  • Persistence Mode: In contrast, persistence mode allows data to be stored on disk, ensuring that it is not lost in the event of a system failure. This mode is ideal for applications that require durability and data recovery, such as e-commerce platforms and financial services.

When to use cache vs persistence mode in Redis?

Use "cache mode" in Redis when you need extremely fast data access for frequently accessed data that can be easily regenerated if lost, while "persistence mode" is appropriate when you need to ensure data durability and recoverability even if the Redis server restarts, typically for scenarios where data loss could be critical or when storing data that takes a long time to re-fetch from a primary source. 

Key points to consider:

  • Cache mode (no persistence):

    • Ideal for temporary data like session information, frequently accessed API results, or dynamic website content. 

    • Provides the best performance due to purely in-memory storage. 

    • Data is lost if the Redis server restarts. 

  • Persistence mode (with RDB or AOF):

    • Necessary when data needs to be preserved across server restarts or failures. 

    • Can impact performance slightly due to disk I/O operations. 

    • Choose RDB for faster recovery from backups, AOF for more complete write logs. 

When to use cache:

  • You need extremely fast data retrieval.

  • Data loss is tolerable, as the data can be regenerated from a primary data source (like a database).  

  • You want to reduce the load on your primary database.

  • Examples:

    • Session management: Storing user login information.

    • Frequently accessed query results.

    • Temporary data, such as real-time analytics.


When to use persistence:

  • Critical application data: If losing data could significantly impact your application functionality. 

  • High availability needs: When you need to quickly recover from a server failure and maintain data consistency. 

  • Long-running sessions: For session data that needs to persist beyond a single user interaction. 

Key Features of IBM Redis

  1. High Performance: IBM Redis is designed for low-latency data access, making it suitable for real-time applications.

  2. Scalability: It can easily scale horizontally to accommodate growing data needs.

  3. Data Structures: Supports various data structures, including strings, hashes, lists, sets, and sorted sets.

  4. Multi-Model Support: Can be used for caching, session storage, and as a message broker.

  5. High Availability: Offers built-in replication and failover capabilities to ensure continuous availability.

  6. Security: Provides robust security features, including encryption and access control.

  7. Integration: Seamlessly integrates with other IBM Cloud services and third-party applications.

Pros and Cons of IBM Redis

Pros:

  • Speed: Extremely fast data access due to in-memory storage.

  • Flexibility: Supports various use cases, from caching to message brokering.

  • Managed Service: Reduces operational overhead as IBM handles maintenance and scaling.

  • Community Support: Backed by a large community of developers and extensive documentation.

Cons:

  • Cost: Managed services can be more expensive than self-hosted solutions.

  • Complexity: May require a learning curve for teams unfamiliar with Redis.

  • Data Size Limitations: In-memory databases are limited by the amount of RAM available.

Comparison with AWS, Azure, and Google Redis Memory Database

| Feature | IBM Redis | AWS ElastiCache | Azure Cache for Redis | Google cloud Memorystore |

|-----------------------|----------------------|----------------------|-----------------------|------------------------|

| Deployment | Fully Managed | Fully Managed | Fully Managed | Fully Managed |

| Persistence | Yes (optional) | Yes (Redis Cluster) | Yes | Yes |

| Scalability | Horizontal | Horizontal | Horizontal | Horizontal |

| Security | Encryption, IAM | VPC, IAM | VNET, RBAC | IAM, VPC |

| Pricing | Pay-as-you-go | Pay-as-you-go | Pay-as-you-go | Pay-as-you-go |

When to Choose IBM Redis Memory Database

IBM Redis is an excellent choice for applications that require high-speed data access and low latency. Here are some real-time use cases:

  1. E-commerce Platforms: For managing product catalogs and user sessions, where quick data retrieval is crucial.

  2. Gaming Applications: To store player scores and game states in real-time.

  3. IoT Applications: For processing and analyzing data from connected devices in real-time.

  4. Financial Services: To handle transactions and user sessions securely and quickly.

  5. High-Performance Caching: Reducing latency by caching frequently accessed data, thereby enhancing application responsiveness.

  6. Session Management: Maintaining user session data in web applications to ensure a seamless user experience.

  7. Real-Time Analytics: Processing and analyzing streaming data in real-time for applications like monitoring dashboards and recommendation engines.

Provisioning IBM Cloud Databases for Redis Using Terraform

To provision an IBM Cloud Databases for Redis instance using Terraform, follow these steps:

  1. Install Terraform: Ensure Terraform is installed on your system.

  2. Configure IBM Cloud Provider: Set up the IBM Cloud Provider plugin for Terraform by creating or retrieving an IBM Cloud API key.

  3. Define Terraform Configuration: Create a Terraform configuration file (main.tf) with the necessary resource definitions.

provider "ibm" {
  ibmcloud_api_key = var.ibmcloud_api_key
  region           = var.region
}

resource "ibm_database" "redis_instance" {
  name             = var.db_name
  plan             = "standard"
  location         = var.region
  service          = "databases-for-redis"
  resource_group   = var.resource_group
  parameters       = jsonencode({
    "members_memory_allocation_mb" = var.memory_allocation_mb
  })
}
  1. Initialize and Apply: Run terraform init to initialize the configuration and terraform apply to create the resources.

Best Practices to Consider

  1. Data Expiration: Set expiration times for cached data to prevent stale data.

  2. Monitoring: Use monitoring tools to track performance and resource usage.

  3. Backup and Recovery: Implement regular backups and a recovery plan for persistent data.

  4. Data Persistence: Enable data persistence to safeguard against data loss during unexpected restarts.

  5. Security Measures: Utilize IAM roles and policies to restrict access, and ensure data encryption is enabled both at rest and in transit.

  6. Monitoring and Alerts: Implement monitoring tools to track performance metrics and set up alerts for critical thresholds to maintain system health.

Conclusion

IBM Redis is a powerful tool for developers looking to enhance application performance through caching and in-memory data storage. By understanding its features, advantages, and best practices, organizations can effectively leverage IBM Redis to meet their data management needs.

Monday, March 3, 2025

IBM Cloud Event Streams: A Comprehensive Overview


IBM cloud Event Streams is a fully managed event streaming platform built on Apache Kafka, designed to handle real-time data feeds with high throughput and low latency. This document delves into the intricacies of IBM Cloud Event Streams, exploring its underlying technology, features, industry use cases, comparisons with similar services from AWS, Azure, and GCP, provisioning and access methods, best practices, cost estimates, and a concluding summary.

What is Cloud Event Streams?

IBM Cloud Event Streams is an event streaming service that allows organizations to process and analyze real-time data streams. It enables the ingestion, storage, and processing of large volumes of data from various sources, facilitating the development of event-driven applications. Built on the robust Apache Kafka framework, Event Streams provides a scalable and resilient platform for managing event data, making it suitable for various applications, including IoT, microservices, and data integration.

Underlying Technology

IBM Cloud Event Streams is fundamentally based on Apache Kafka, an open-source distributed event streaming platform. Kafka is designed for high-throughput, fault-tolerant, and scalable data streaming. It uses a publish-subscribe model, where producers send messages to topics, and consumers read messages from those topics. The architecture consists of brokers, producers, consumers, and topics, allowing for efficient data handling and processing.

Features: Pros and Cons

Features

  1. Scalability: Event Streams can scale horizontally, allowing users to handle increased data loads seamlessly.

  2. High Availability: The service ensures data durability and availability through replication and partitioning.

  3. Managed Service: IBM Cloud Event Streams is a fully managed service, reducing operational overhead for users.

  4. Integration: It integrates well with various IBM Cloud services and third-party applications.

  5. Security: The platform provides robust security features, including encryption and access control.

  6. Monitoring and Analytics: Built-in monitoring tools help track performance and usage metrics.

Pros

  • Simplifies event-driven architecture implementation.

  • Reduces the complexity of managing Kafka clusters.

  • Offers enterprise-grade security and compliance features.

  • Provides a rich ecosystem of connectors for data integration.

Cons

  • Pricing may be a concern for small-scale applications.

  • Learning curve for users unfamiliar with Kafka concepts.

  • Limited customization compared to self-managed Kafka deployments.

Industry Use Cases

  1. IoT Applications: Collecting and processing data from IoT devices in real-time for analytics and monitoring.

  2. Microservices Communication: Enabling asynchronous communication between microservices in a cloud-native architecture.

  3. Log Aggregation: Centralizing logs from various applications for real-time analysis and troubleshooting.

  4. Data Integration: Streaming data between different systems and applications for real-time data synchronization.

  5. Real-Time Analytics: Event Streams enables immediate processing and analysis of streaming data, allowing businesses to gain timely insights and make data-driven decisions.

  6. Event-Driven Architectures: Event Streams supports the development of responsive systems that react to events as they occur, enhancing operational efficiency and enabling real-time processing.

Architecture Diagram on file based Event Driven 


Comparison with Similar Services

When comparing IBM Event Streams with services like AWS Kinesis, Azure Event Hubs, and Google Cloud Pub/Sub, each offers unique strengths:

  • AWS Kinesis: Excels in real-time processing, making it suitable for applications requiring immediate data handling.

  • Azure Event Hubs: Provides robust integration capabilities, supporting seamless connections with various applications and services.

  • Google Cloud Pub/Sub: Offers a fully managed, scalable messaging service designed to integrate with Google Cloud's ecosystem.

How to Provision and Access It

Provisioning and accessing IBM Cloud Event Streams through Terraform enables Infrastructure as Code (IaC) practices, allowing for consistent and automated deployments. Below is a detailed guide on how to achieve this, along with example code snippets.

1. Prerequisites

Before you begin, ensure you have the following:

  • IBM Cloud Account: An active IBM Cloud account.

  • IBM Cloud API Key: Generate an API key from the IBM Cloud console.

  • Terraform Installed: Ensure Terraform is installed on your machine. You can download it from the Terraform website.

  • IBM Cloud Terraform Provider: Configure the IBM Cloud provider in Terraform.

2. Configure the IBM Cloud Provider in Terraform

Create a main.tf file and define the IBM Cloud provider:

provider "ibm" {
  ibmcloud_api_key = var.ibmcloud_api_key
  region           = var.region
}

Ensure you have variables defined for ibmcloud_api_key and region. You can set these in a variables.tf file:

variable "ibmcloud_api_key" {
  description = "IBM Cloud API Key"
  type        = string
}

variable "region" {
  description = "IBM Cloud region"
  type        = string
  default     = "us-south"
}

3. Provision an Event Streams Instance

Add the following resource block to your main.tf to create an Event Streams instance:

resource "ibm_resource_instance" "event_streams_instance" {
  name          = "my-event-streams-instance"
  service       = "event-streams"
  plan          = "standard"
  location      = var.region
  resource_group = ibm_resource_group.resource_group.id
}

This configuration specifies the creation of an Event Streams instance with the standard plan in the specified region.

4. Create a Topic

To create a topic within the Event Streams instance, you can use the following resource:

resource "ibm_event_streams_topic" "topic" {
  name               = "my-topic"
  partitions         = 3
  retention_hours    = 24
  event_streams_id   = ibm_resource_instance.event_streams_instance.id
}

This creates a topic named "my-topic" with 3 partitions and a retention period of 24 hours.

5. Apply the Terraform Configuration

Initialize Terraform and apply the configuration:

terraform init
terraform apply

Confirm the apply step when prompted.

6. Accessing Event Streams

After provisioning, you can access the Event Streams instance through the IBM Cloud console or by using the provided credentials in your Terraform output.

7. Example Repository

For a comprehensive example, refer to the IBM Cloud Terraform Provider Examples repository, which includes detailed configurations and additional resources.

By following these steps, you can effectively provision and manage IBM Cloud Event Streams instances using Terraform, enabling automated and consistent infrastructure deployments.

Best Practices

  1. Topic Design: Carefully design topics to optimize data organization and retrieval.

  2. Data Retention Policies: Set appropriate data retention policies based on use case requirements.

  3. Monitoring: Utilize monitoring tools to track performance and identify bottlenecks.

  4. Security: Implement robust security measures, including access controls and encryption.

  5. Testing: Regularly test the system under load to ensure it meets performance expectations.

Cost Estimate

The cost of using IBM Cloud Event Streams varies based on factors such as the number of partitions, data retention period, and data transfer. IBM provides a pricing calculator to estimate costs based on specific usage scenarios. Generally, costs are incurred for provisioned capacity, data storage, and data transfer.

IBM Event Streams offers various pricing plans:

  • Lite Plan: Free access with limited features, suitable for development and testing purposes.

  • Standard Plan: Pay-as-you-go model, charging per partition-hour and additional fees for outbound data consumption.

Sample Code

To illustrate how to produce and consume messages using IBM Event Streams, consider the following example using the confluent-kafka Python library. This example demonstrates how to send and receive messages to and from an Event Streams topic.

Producer Example:

from confluent_kafka import Producer

# Configuration
conf = {
    'bootstrap.servers': 'your_bootstrap_servers',
    'security.protocol': 'SASL_SSL',
    'sasl.mechanisms': 'PLAIN',
    'sasl.username': 'your_api_key',
    'sasl.password': 'your_api_secret',
}

# Create Producer instance
producer = Producer(conf)

# Delivery callback
def delivery_callback(err, msg):
    if err:
        print(f'Message failed delivery: {err}')
    else:
        print(f'Message delivered to {msg.topic()} [{msg.partition()}]')

# Produce a message
producer.produce('your_topic', key='key', value='value', callback=delivery_callback)

# Wait for any outstanding messages to be delivered
producer.flush()

Consumer Example in python:

from confluent_kafka import Consumer, KafkaException

# Configuration
conf = {
    'bootstrap.servers': 'your_bootstrap_servers',
    'security.protocol': 'SASL_SSL',
    'sasl.mechanisms': 'PLAIN',
    'sasl.username': 'your_api_key',
    'sasl.password': 'your_api_secret',

::contentReference[oaicite:11]{index=11}
 

Conclusion

IBM Cloud Event Streams is a powerful event streaming platform that leverages the capabilities of Apache Kafka to provide a scalable, secure, and fully managed service for real-time data processing. Its rich feature set, combined with its integration capabilities and industry use cases, makes it a compelling choice for organizations looking to implement event-driven architectures. While it competes with similar services from AWS, Azure, and GCP, its unique strengths and managed nature position it as a valuable tool for modern data-driven applications.

Sunday, March 2, 2025

IBM Cloud Code Engine : Run a Container


IBM Cloud Code Engine is a fully managed serverless platform that allows developers to build, deploy, and manage applications and workloads without the need to manage the underlying infrastructure. This document provides an overview of IBM Cloud Code Engine, its features, and how it can benefit developers looking to streamline their application development process.


Overview

IBM Cloud Code Engine simplifies the application development lifecycle by providing a serverless environment where developers can focus on writing code rather than managing servers. It supports various workloads, including containerized applications, batch jobs, and event-driven functions. With its pay-as-you-go pricing model, developers only pay for the resources they consume, making it a cost-effective solution for deploying applications.

Key Features

1. Serverless Architecture

IBM Cloud Code Engine abstracts away the infrastructure management, allowing developers to deploy applications without worrying about provisioning or scaling servers. This enables rapid development and deployment cycles.

2. Support for Multiple Workloads

Whether you are building microservices, running batch jobs, or creating event-driven functions, Code Engine supports a variety of workloads, making it versatile for different application needs.

3. Containerization Application

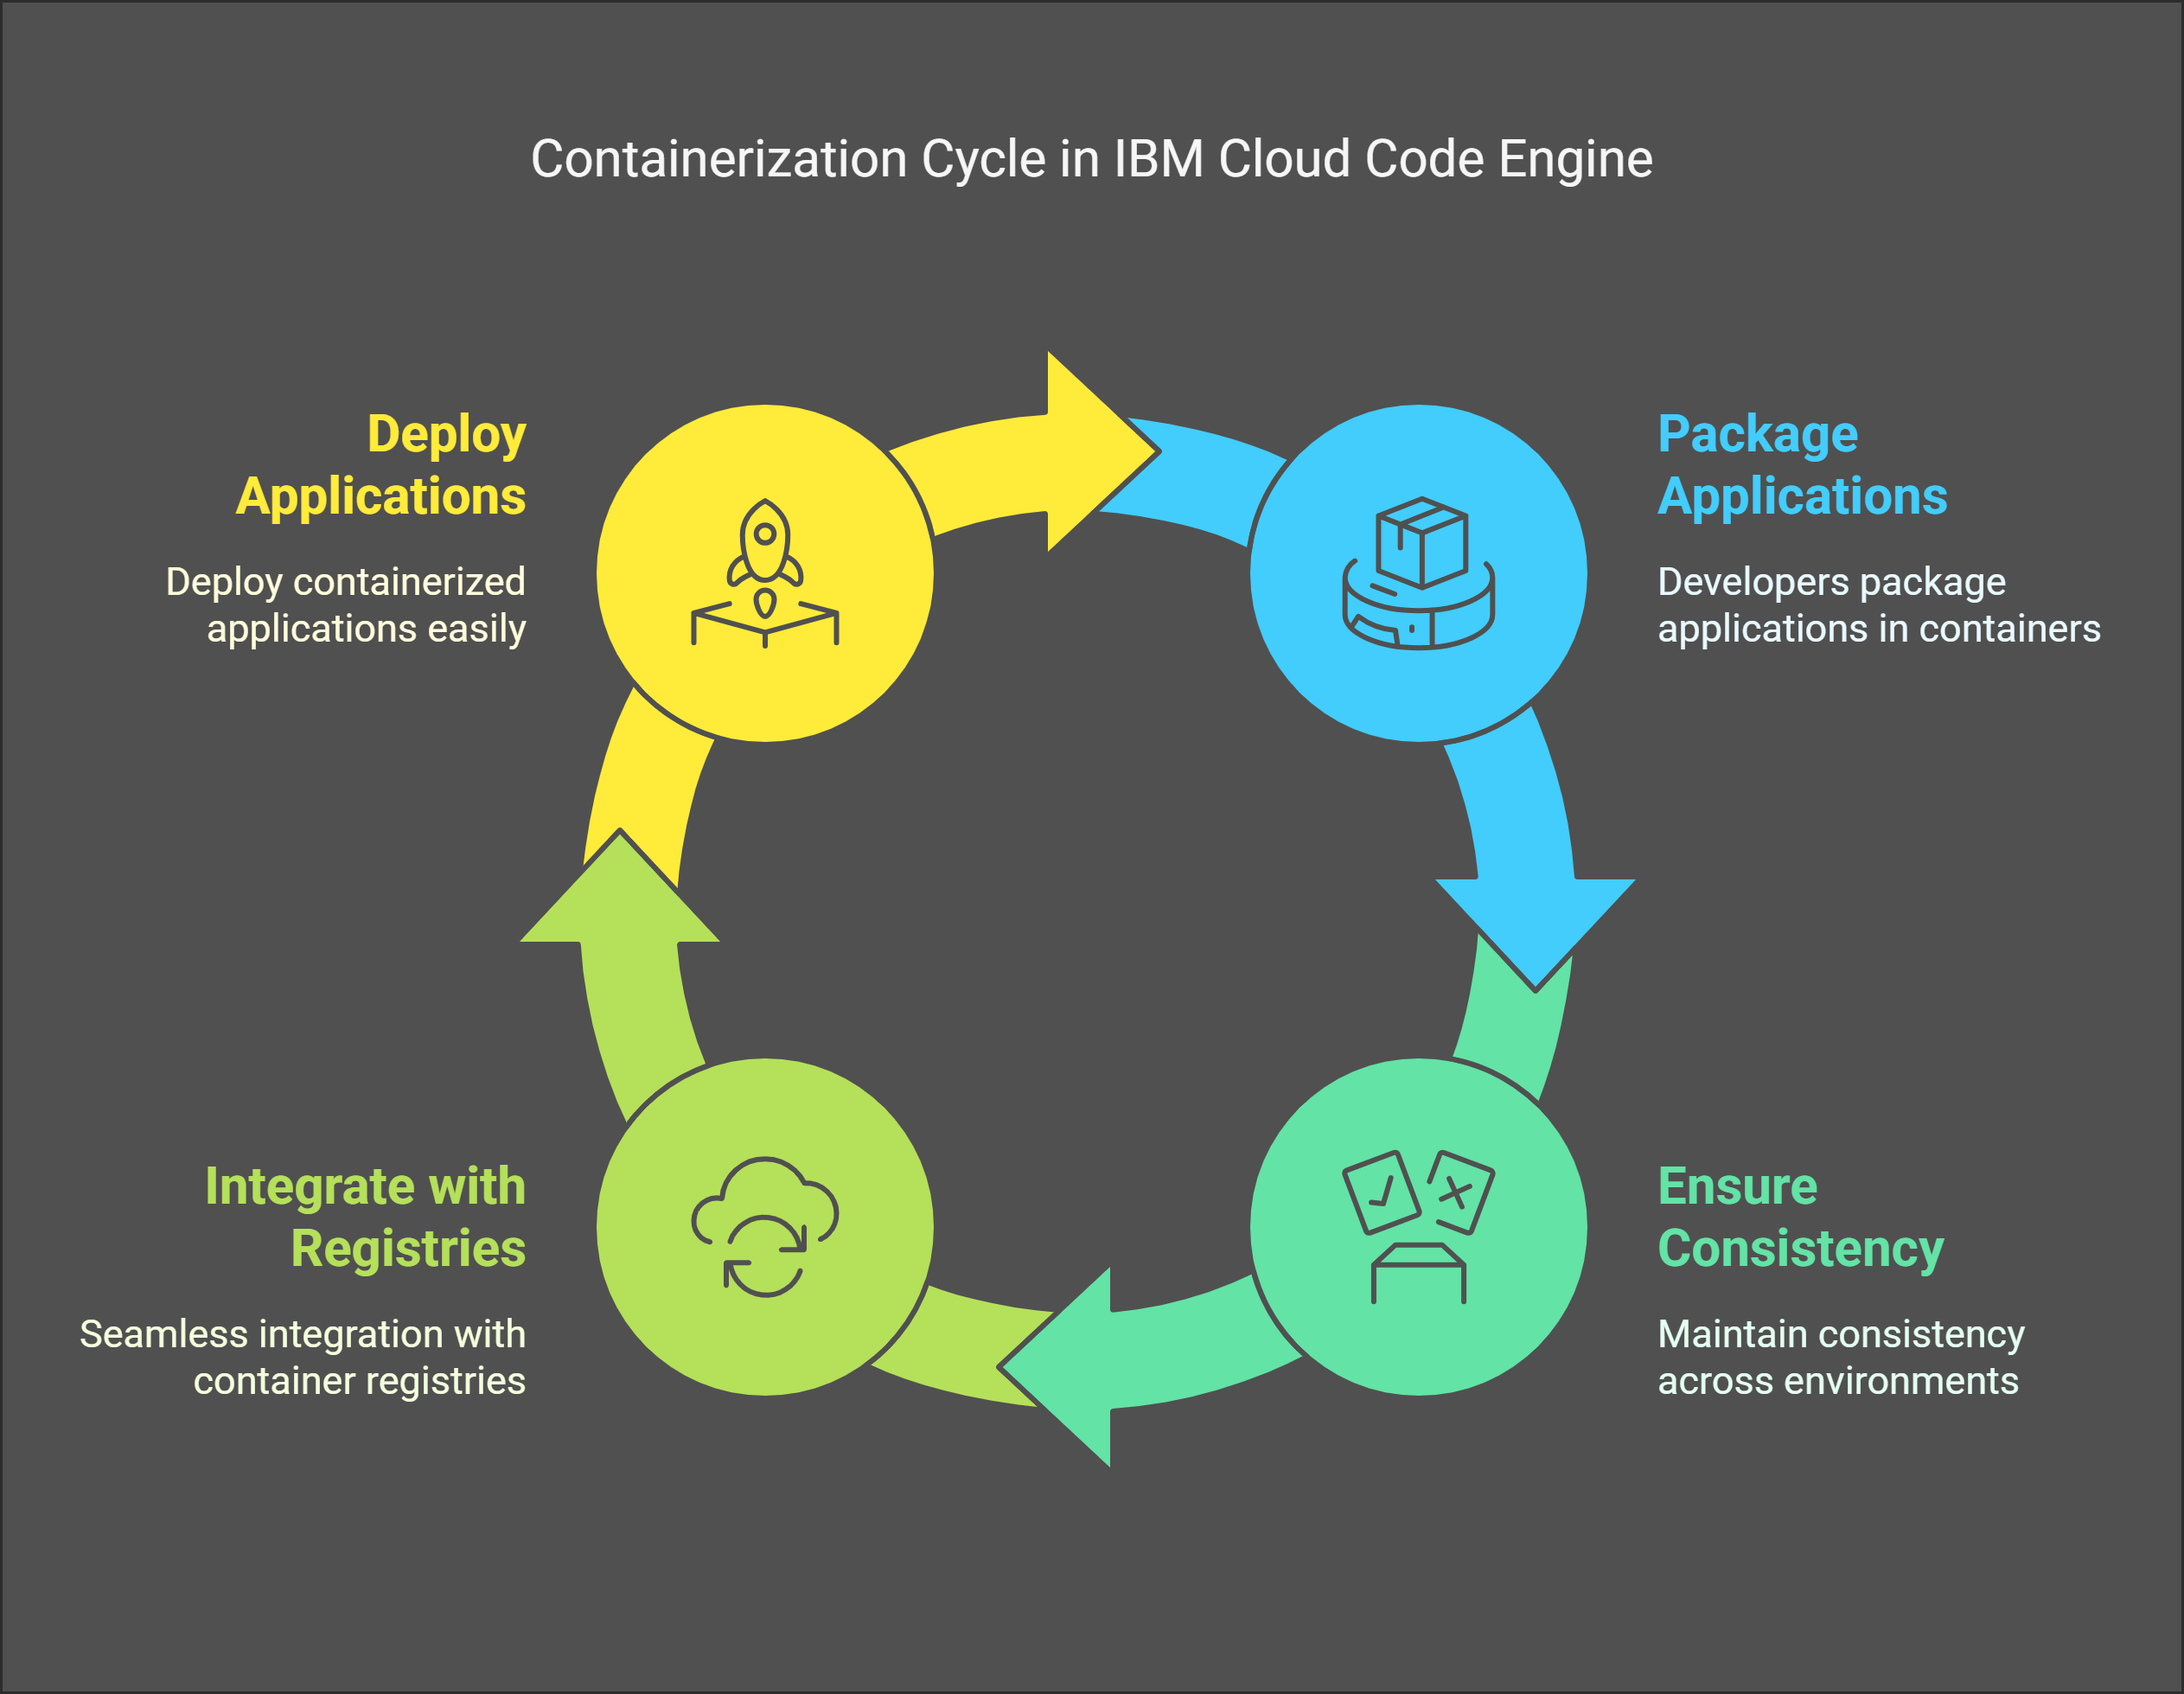
Developers can package their applications in containers, ensuring consistency across development, testing, and production environments. Code Engine seamlessly integrates with container registries, making it easy to deploy containerized applications.

4. Event-Driven Capabilities through batch job

Code Engine can respond to events from various sources, such as cloud storage changes or message queues, allowing developers to create reactive applications that respond to real-time data.

5. Integrated CI/CD

With built-in continuous integration and continuous deployment (CI/CD) capabilities, developers can automate their deployment processes, ensuring that new features and updates are delivered quickly and reliably.

6. Monitoring and Logging

IBM Cloud Code Engine provides monitoring and logging tools to help developers track application performance and troubleshoot issues effectively.


Code Engine Instance


1) Container Applications

Overview

Container applications are executable units of software where application code is packaged with its libraries and dependencies. They are designed to run consistently across different environments, such as development, testing, and production.

Use Cases

  1. Microservices Architecture: Container applications are ideal for microservices, where each service can be developed, deployed, and scaled independently.

  2. DevOps and CI/CD Pipelines: Containers streamline the development and deployment process, making it easier to implement continuous integration and continuous deployment (CI/CD) pipelines.

  3. Hybrid Cloud Deployments: Containers provide portability, allowing applications to run seamlessly across on-premises and cloud environments.

Example

A retail company uses container applications to deploy its e-commerce platform. Each microservice, such as user authentication, product catalogue, and payment processing, runs in its own container, ensuring scalability and fault isolation.

2) Batch Jobs

Overview

Batch jobs are designed to process large volumes of data in predefined batches. They are typically used for tasks that do not require immediate processing and can be scheduled to run at specific intervals.

Use Cases

  1. Data Processing: Batch jobs are used for ETL (Extract, Transform, Load) processes, where large datasets are processed and transformed for analytics.

  2. Report Generation: Automated generation of reports, such as financial statements or inventory summaries, can be efficiently handled by batch jobs.

  3. System Maintenance: Tasks like database backups, log file archiving, and system updates can be scheduled as batch jobs during off-peak hours.

Example

A financial services company uses batch jobs to process end-of-day transactions. The batch job aggregates transaction data performs necessary calculations and generates daily financial reports.

3) Functions

Overview

Functions are stateless code snippets that perform specific tasks in response to events. They are designed to be lightweight and can scale automatically based on demand.

Use Cases

  1. Event-Driven Processing: Functions can be triggered by events such as file uploads, database changes, or HTTP requests, making them suitable for real-time data processing.

  2. IoT Data Processing: Functions can process data from IoT devices, such as sensor readings or device status updates, and perform actions based on the data.

  3. Automated Workflows: Functions can be used to automate workflows, such as sending notifications, starting backups, or processing user inputs.

Example

An e-commerce platform uses functions to send order confirmation emails. When a user places an order, an event triggers a function that generates and sends the email with order details.

How IBM Code Engine Scaling?

IBM Code Engine handles scaling automatically, ensuring that your applications can handle varying loads without manual intervention. Here's how it works:

Automatic Scaling

IBM Code Engine automatically scales the number of running instances of an application based on the incoming workload. This means that if the demand increases, more instances are created to handle the load, and if the demand decreases, the number of instances is reduced, potentially down to zero.

Concurrency Settings

The platform uses concurrency settings to determine the number of simultaneous requests that can be processed by each instance of an application. When the number of requests exceeds the concurrency limit, additional instances are created to handle the excess load.

Scaling to Zero

One of the key features of IBM Code Engine is its ability to scale applications down to zero instances when there are no incoming requests. This helps in reducing costs as you only pay for the resources you consume.

Scale-Down Delay

To prevent instances from exiting prematurely and to handle ongoing application loads, IBM Code Engine allows you to configure a "scale-down delay." This parameter gives application instances more time to live during temporary drops in incoming requests, ensuring smoother performance.

Load Balancing

IBM Code Engine also takes care of load balancing by distributing incoming requests across all running instances of an application. This ensures that no single instance is overwhelmed and helps in maintaining optimal performance.

Example

Imagine you have an e-commerce application running on IBM Code Engine. During peak shopping hours, the platform automatically scales up the number of instances to handle the increased traffic. Once the traffic subsides, it scales down the instances, potentially to zero, saving costs while ensuring that the application is always ready to handle new requests.

IBM Code Engine's automatic scaling capabilities make it an efficient and cost-effective solution for running containerized workloads

Benefits

  • Cost Efficiency: The pay-as-you-go model ensures that developers only pay for the resources they use, reducing overall costs.

  • Faster Time to Market: By eliminating the need for infrastructure management, developers can focus on building and deploying applications quickly.

  • Scalability: Code Engine automatically scales applications based on demand, ensuring optimal performance without manual intervention.

  • Flexibility: Support for various programming languages and frameworks allows developers to use the tools they are most comfortable with.

Disadvantages

  1. Cost Uncertainty: The automatic scaling feature is great for handling varying workloads, but it can make cost prediction challenging. If not carefully monitored, costs can quickly escalate with increased usage.

  2. Limited Customization: IBM Code Engine abstracts much of the underlying infrastructure, which simplifies management but can limit customization. Users with specific requirements may find it less flexible compared to managing their own infrastructure.

  3. Learning Curve: While IBM Code Engine simplifies many aspects of application deployment, there is still a learning curve, especially for those unfamiliar with containerization, Kubernetes, or serverless architectures.

  4. Dependency Management: Deploying applications with complex dependencies might require additional configuration and testing to ensure compatibility and performance within the platform.

  5. Potential Vendor Lock-In: Relying heavily on IBM Code Engine for all workloads could lead to vendor lock-in, making it difficult to switch to a different provider or platform in the future without significant effort.


Binding a service instance to an app, job, or function workload

To bind an IBM Code Engine instance to an app, job, or function workload, you typically need to follow these steps using IBM Cloud's Code Engine service. Here's a general process for binding an IBM Code Engine instance to your workloads:

1. Create or Configure an IBM Cloud Code Engine Project

  • Start by creating an IBM Cloud Code Engine project if you haven’t already.
  • In IBM Cloud, Code Engine projects help organize workloads, such as apps, jobs, and functions.
ibmcloud ce project create --name <project-name>

2. Create the Workload (App, Job, or Function)

  • For Apps: Deploy a containerized application or use a code artifact.
  • For Jobs: Deploy batch jobs or tasks that run to completion.
  • For Functions: Deploy serverless functions that are invoked on demand.

Example (App):

ibmcloud ce app create --name <app-name> --image <image-url> --env <env-vars> --port <port>

Example (Job):

ibmcloud ce job create --name <job-name> --image <image-url> --env <env-vars>

Example (Function):

ibmcloud ce function create --name <function-name> --image <image-url> --env <env-vars>

3. Bind Resources (Optional)

Code Engine allows you to bind external resources to your workloads. You can bind resources such as databases, secrets, and IAM roles, depending on your workload type.

For example, if you need to bind a service such as Cloudant or Db2 to an app:

  • First, create the resource:

    ibmcloud resource service-instance-create <service-name> <service-type> <plan> --location <region>
    
  • Then, bind the service instance to the workload (app, job, or function):

    ibmcloud ce app bind-service --name <app-name> --service <service-name>
    

You may also use environment variables to pass credentials and configurations to your workload.

4. Binding Environment Variables (Optional)

You can bind environment variables to your app, job, or function workload. This can include credentials, configuration settings, or connection strings.

Example:

ibmcloud ce app update --name <app-name> --env MY_VARIABLE=value

5. Check the Binding

After binding resources or environment variables, ensure that the connection is established and working by checking the status of your workload.

Example:

ibmcloud ce app get --name <app-name>

Example Full Command for Binding to an App:

# Create a project
ibmcloud ce project create --name my-project

# Create an app
ibmcloud ce app create --name my-app --image my-image --port 8080

# Create a database service
ibmcloud resource service-instance-create my-db db2free lite --location us-south

# Bind the service to the app
ibmcloud ce app bind-service --name my-app --service my-db

# Update app with environment variables
ibmcloud ce app update --name my-app --env DB_URL=my-db-url

6. Deploy and Monitor

Once you’ve set up the binding, deploy your app or job and monitor the logs to ensure everything is working correctly.

Example (View Logs):

ibmcloud ce app logs --name <app-name>

By binding IBM Code Engine workloads to external services or resources (such as databases, secrets, and environment variables), you can enhance the functionality of your apps, jobs, and functions.


Conclusion

IBM Cloud Code Engine is a powerful platform for developers looking to leverage serverless architecture for their applications. Its robust features and cost-effective pricing model provide an ideal environment for building, deploying, and managing modern applications. By adopting Code Engine, developers can enhance their productivity and focus on delivering value to their users.

Building a Scalable, Production-Grade Notification Service with Spring Boot & Kafka

Modern microservices architectures require a centralized, reliable, and fault-tolerant notification engine. Whether you are sending transact...